Recover Agent Memory on Any Machine with Snapshots and Pointers
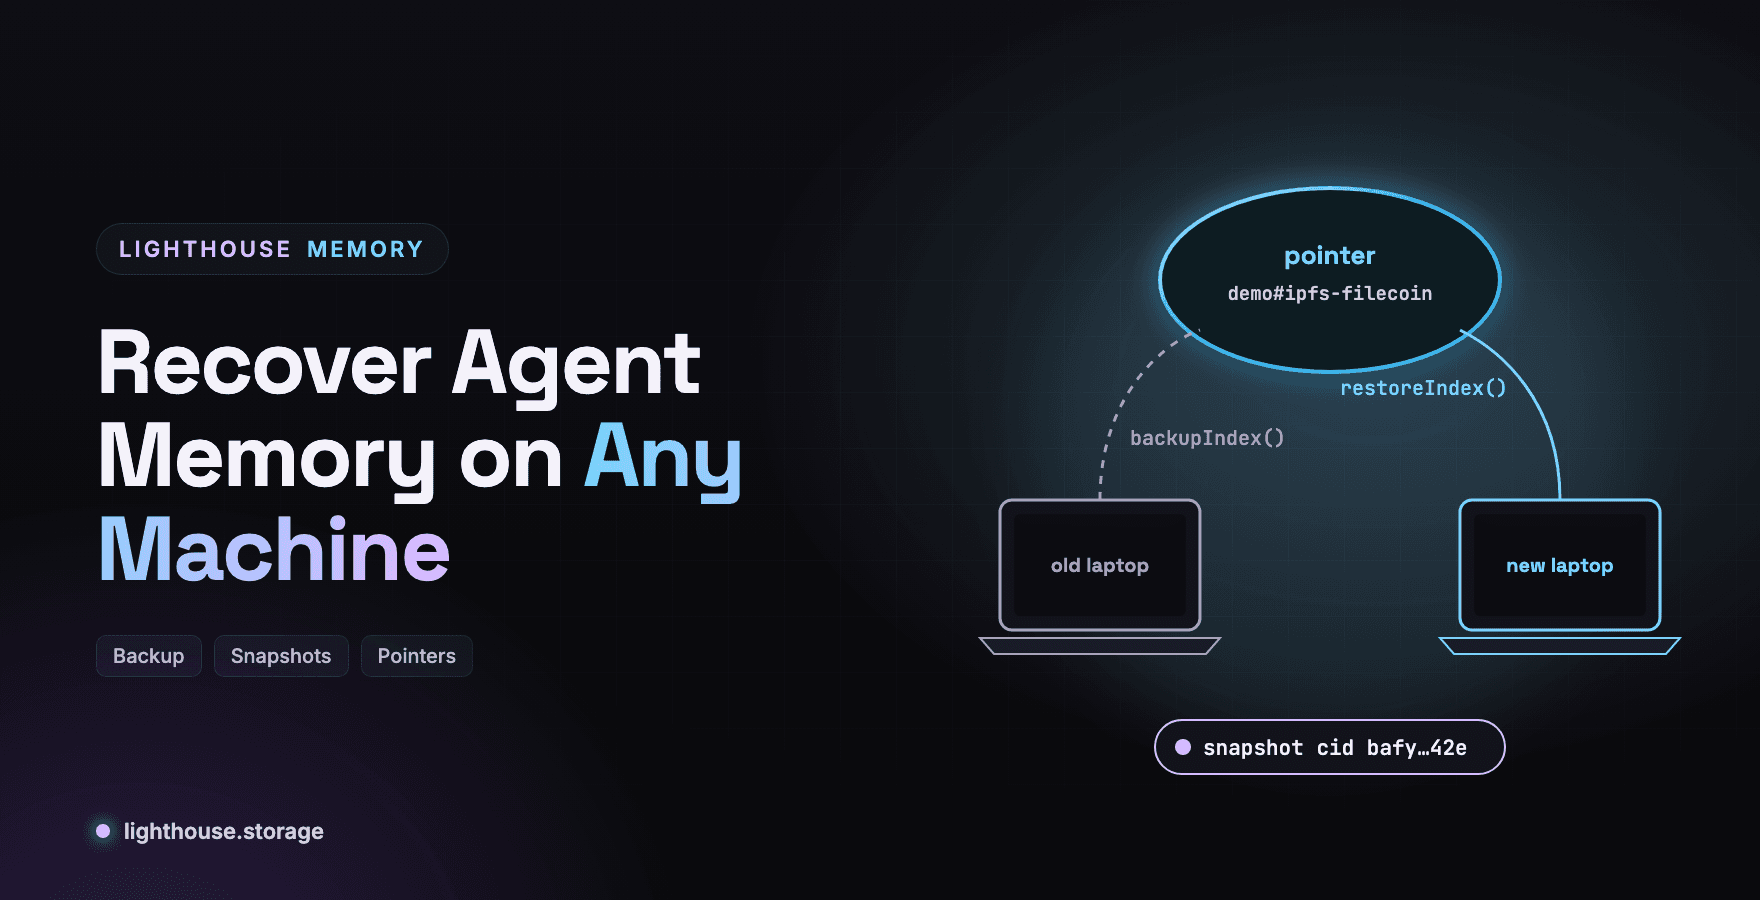
An agent's memory is only durable if you can get it back. New laptop, crashed container, fresh deploy: the question is how many steps stand between an empty machine and an agent that remembers everything.
With most memory systems, the answer is "restore the database backup, if someone took one." Lighthouse Memory is designed so the answer is two calls, because the memory never lived on the machine in the first place.
This tutorial covers the three recovery paths, when to use each, and how to set up automatic cross device backup.
The Core Idea: The Local Index Is a Cache
Lighthouse Memory keeps a local index in .memory-sdk/<namespace>.index.json so recall is fast and runs without network round trips. It is tempting to think of that file as "the memory." It is not.
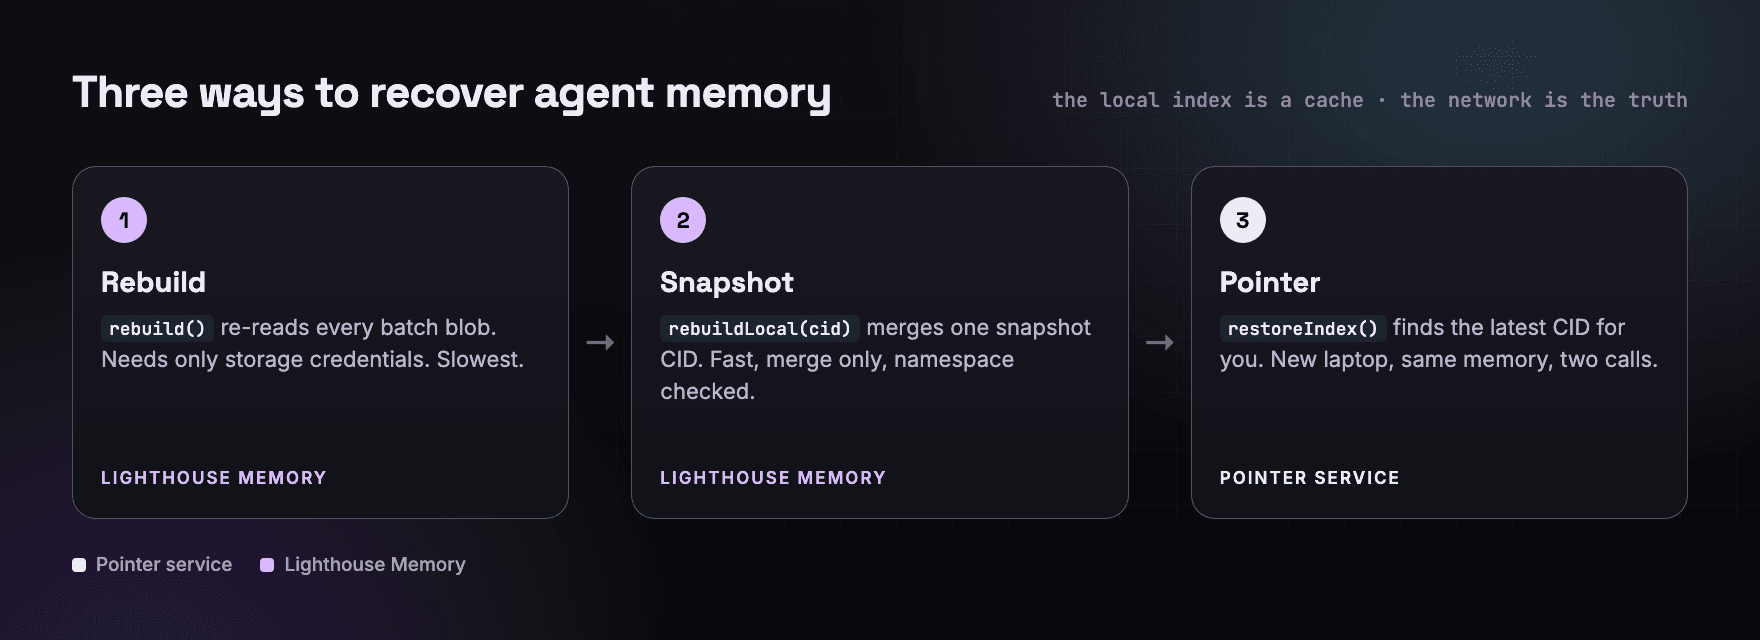
The local index is a cache. The source of truth is on the network.
Memories are flushed as content addressed batch blobs to Filecoin, Walrus, S3 or another storage. Anything on the network can rebuild the index. The recovery question is only about speed and bookkeeping.
Path 1: Rebuild From Storage
The slowest path needs the least: only your storage credentials.
// batched engine
const result = await memory.rebuild()
// { restored: 42, source: 'blobs' }
rebuild() lists every mem-batch.<namespace>.* blob in storage, re-reads them in createdAt order, removes duplicates by ID, and replaces the local index. No pointer or CID is needed.
The cost grows with history, because every blob is fetched. On S3, listing is cheap, so rebuild is usually faster there than on Walrus or Filecoin.
For the memwal engine, the equivalent asks the relayer to repair its vector index from onchain data:
await memory.restore({ maxBlobs: 200 }) // { restored, skipped, total, calls }
Path 2: Restore From One Snapshot CID
The fast path. snapshotIndex() pins the entire local index, including pending memories, as one blob and returns one CID.
const snap = await memory.snapshotIndex()
// batched: { cid: 'baf…', entries: 42, gatewayUrl: 'https://…' }
On any other machine, construct an engine with the same namespace and merge it:
const fresh = new BatchedEngine(storage, { namespace: 'demo', embedder })
await fresh.rebuildLocal(snap.cid)
// { added: 42, total: 42 }
Three safety properties come built in:
- Merge only. Entries this machine already has are skipped, so rebuilding onto a partly populated index is safe.
- Namespace checked. A snapshot for
alicewill not load intobob; the SDK throws instead of mixing data. - Network checked on memwal. A mainnet snapshot will not load into a testnet store.
Snapshots are also how you hand context between agents. See One Memory Layer Shared Across Every AI Model.
Path 3: The Pointer Service, for Cross Device Memory
Snapshots fix speed. They leave one problem: someone has to know the latest CID. The pointer service solves that bookkeeping. It maps each user, namespace and network to the latest snapshot CID, with a pointer key of <namespace>#<network>, so a fresh device finds its memory without anyone copying a CID.
Set up once
npm install @lighthouse-ai/cloud-sync dotenv
npx -y @lighthouse-ai/cloud-sync login   # saves the session token to ~/.memory-sdk-cloud/token (0600)
# .env
CM_API_URL=https://memory-api.lighthouse.storage
Back up
import { backupIndex } from '@lighthouse-ai/cloud-sync'

const out = await backupIndex(memory, {
  apiUrl: process.env.CM_API_URL,
  namespace: 'demo',
  network: 'ipfs-filecoin',
  engine: 'batched',
})
// { cid: 'baf…', pointer: { pointerKey: 'demo#ipfs-filecoin', snapshotCid, memories, updatedAt, … } }
Run it after important sessions, or on a schedule. Each backup overwrites the previous pointer; the current version keeps the latest CID per namespace and network.
Restore on a new machine
import { restoreIndex } from '@lighthouse-ai/cloud-sync'

const out = await restoreIndex(freshMemory, {
  apiUrl: process.env.CM_API_URL,
  namespace: 'demo',
  network: 'ipfs-filecoin',
})
// { cid: 'baf…', result: { added: 42, total: 42 } }
The CID never appears in the restore code. That is the point: new laptop, same memory, in two calls.
The same pair works for both engines, because batched and memwal both implement snapshotIndex() and rebuildLocal().
Choosing a Path
| Situation | Call | Needs |
|---|---|---|
| New device, pointer backed up | restoreIndex() | API URL, session token, storage credentials |
| New device, no pointer | rebuild() (batched) or restore() (memwal) | Storage or relayer credentials only |
| You have a CID from chat, docs or logs | rebuildLocal(cid) | Storage credentials and the CID |
| Pointer service unreachable | rebuildLocal(cid) with a CID you kept | Same as above |
The Durability Model
Recovery is easy only if memory reached the network first. This table from the docs is worth pinning to the wall.
| Failure | Recovery |
|---|---|
| Session ends | Batched: flushed memories are on storage and pending ones are in the local index, so nothing is lost. Memwal: everything is already on the relayer |
| Machine lost before flush (batched) | Pending memories are gone. Flush before important sessions end, or set MEMORYFLUSHEVERY=1 |
| Local index deleted | rebuild() or restore(), or instantly with rebuildLocal(snapshotCid) |
| Snapshots unreadable | Batched falls back to rebuild() from blobs |
| New machine | Storage credentials plus rebuild(), or storage credentials plus pointer token plus restoreIndex() |
The single most important habit: call flush() before an important session ends. Everything else is recoverable.
Two Things to Know About Snapshots
Snapshots are plaintext. Like batch blobs and pinned memwal mirrors, anyone with the snapshot CID can read it. The pointer service stores only the CID, never the contents, but treat snapshot CIDs as sensitive if the memory is. For sensitive namespaces, use the memwal engine and rely on the relayer rather than published snapshots. See Encrypted Memory for AI Agents with Memwal and SEAL.
Snapshots are checkpoints. Every snapshot CID is a complete, tamper evident picture of memory at one moment. Keep them, and you can load last month's memory into a clean engine to see what an agent knew then. See How to Audit and Monitor AI Agents with Verifiable Memory. For a public, onchain version of the pointer, see Onchain Agent Memory on Robinhood Chain with Smart Contracts.
Troubleshooting
| Symptom | Fix |
|---|---|
No snapshot saved for namespace … yet (404) | Run a backup first; restore cannot invent a pointer |
Snapshot is for "alice", but this engine is "bob" | Namespace mismatch; align the namespace |
Missing Clerk session JWT | Run the cloud-sync login once, or pass token explicitly |
rebuild() returns 0 | Wrong namespace or wrong storage network; they never mix |
rebuild() is slow | Expected; use snapshots for the fast path |
Frequently Asked Questions
How do I back up AI agent memory?
Call snapshotIndex() to get one CID for the whole memory, and save it with the pointer service using backupIndex() from @lighthouse-ai/cloud-sync.
How do I restore agent memory on a new machine?
Call restoreIndex() with the same namespace and network. It fetches the latest snapshot CID and merges it with rebuildLocal().
What if I never took a snapshot?
Use rebuild() on the batched engine to re-read every batch blob from storage, or restore() on memwal.
Can memory be lost?
Only pending memories on the batched engine that were never flushed. Flush before sessions end or set flushEvery to 1.
Does restoring overwrite local memories?
No. rebuildLocal() merges and skips IDs already present.
Get Started
The concepts behind all of this: Lighthouse Memory Concepts Explained for Developers.
Stay in Touch
Learn more at the website, docs, or GitHub. Join the community on Discord, X, Telegram, and LinkedIn.