Composable Memory for AI Agents on S3 R2 and Open Source Models
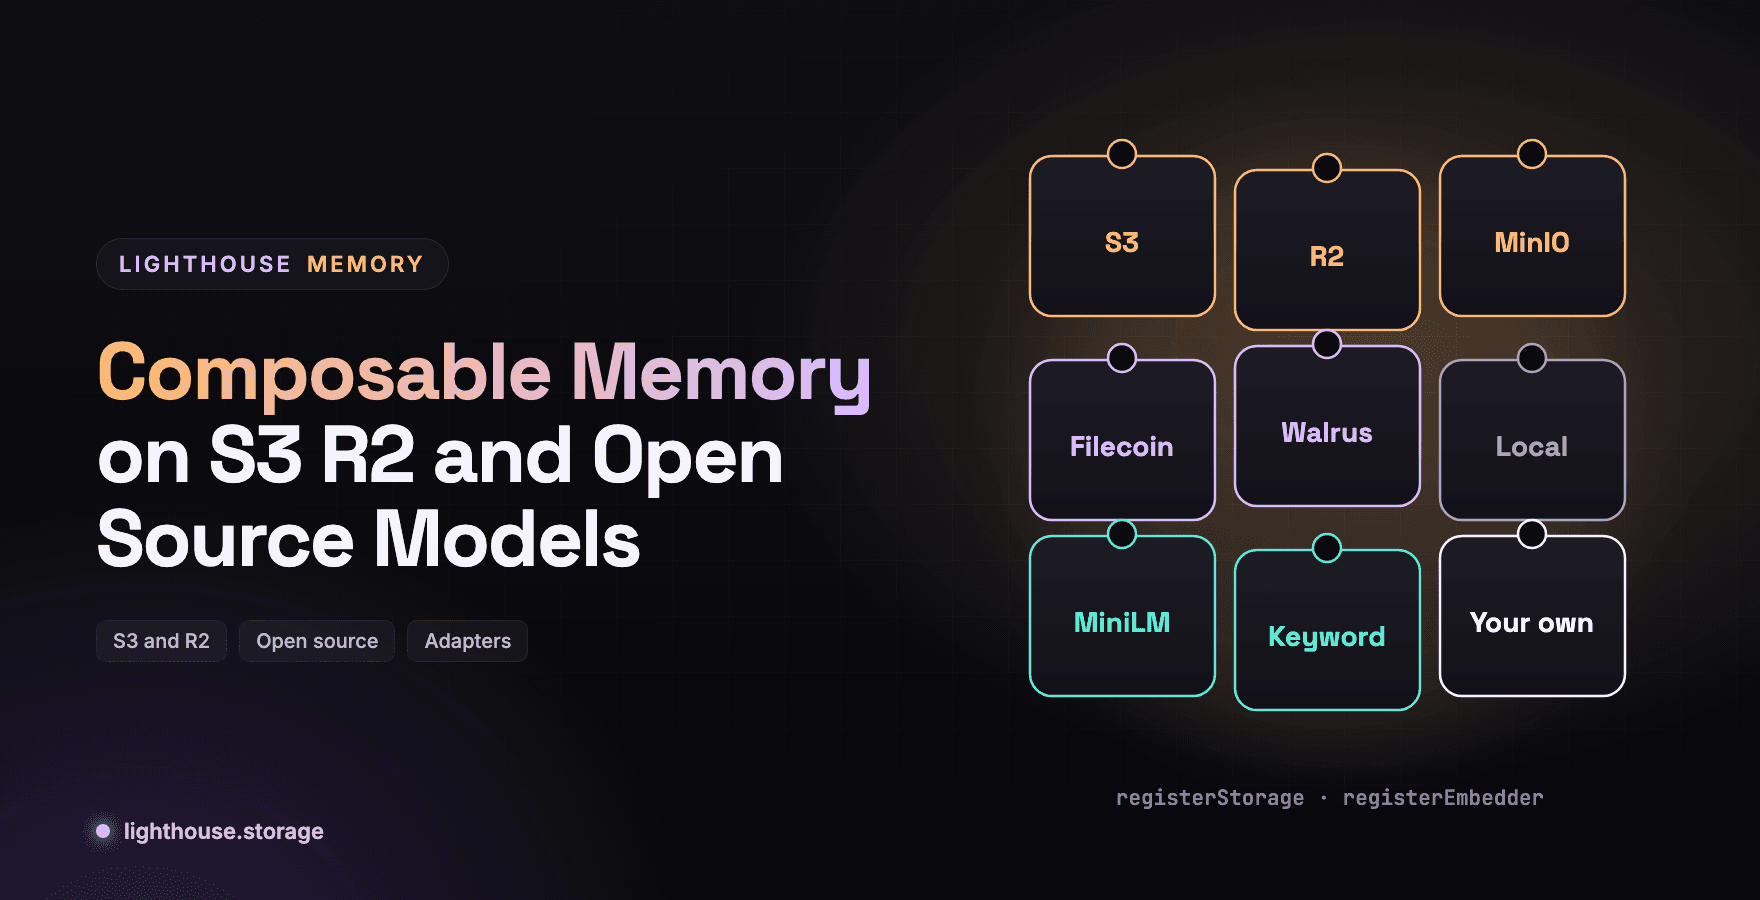
Most agent memory products make one choice for you: their cloud, their embedding API, their database. Composable memory lets you make those choices yourself, and change them later without rewriting your agent.
Enterprises already have storage they trust, compliance rules about where data lives, and opinions about which models they will send data to. A memory layer that ignores all of that does not get deployed.
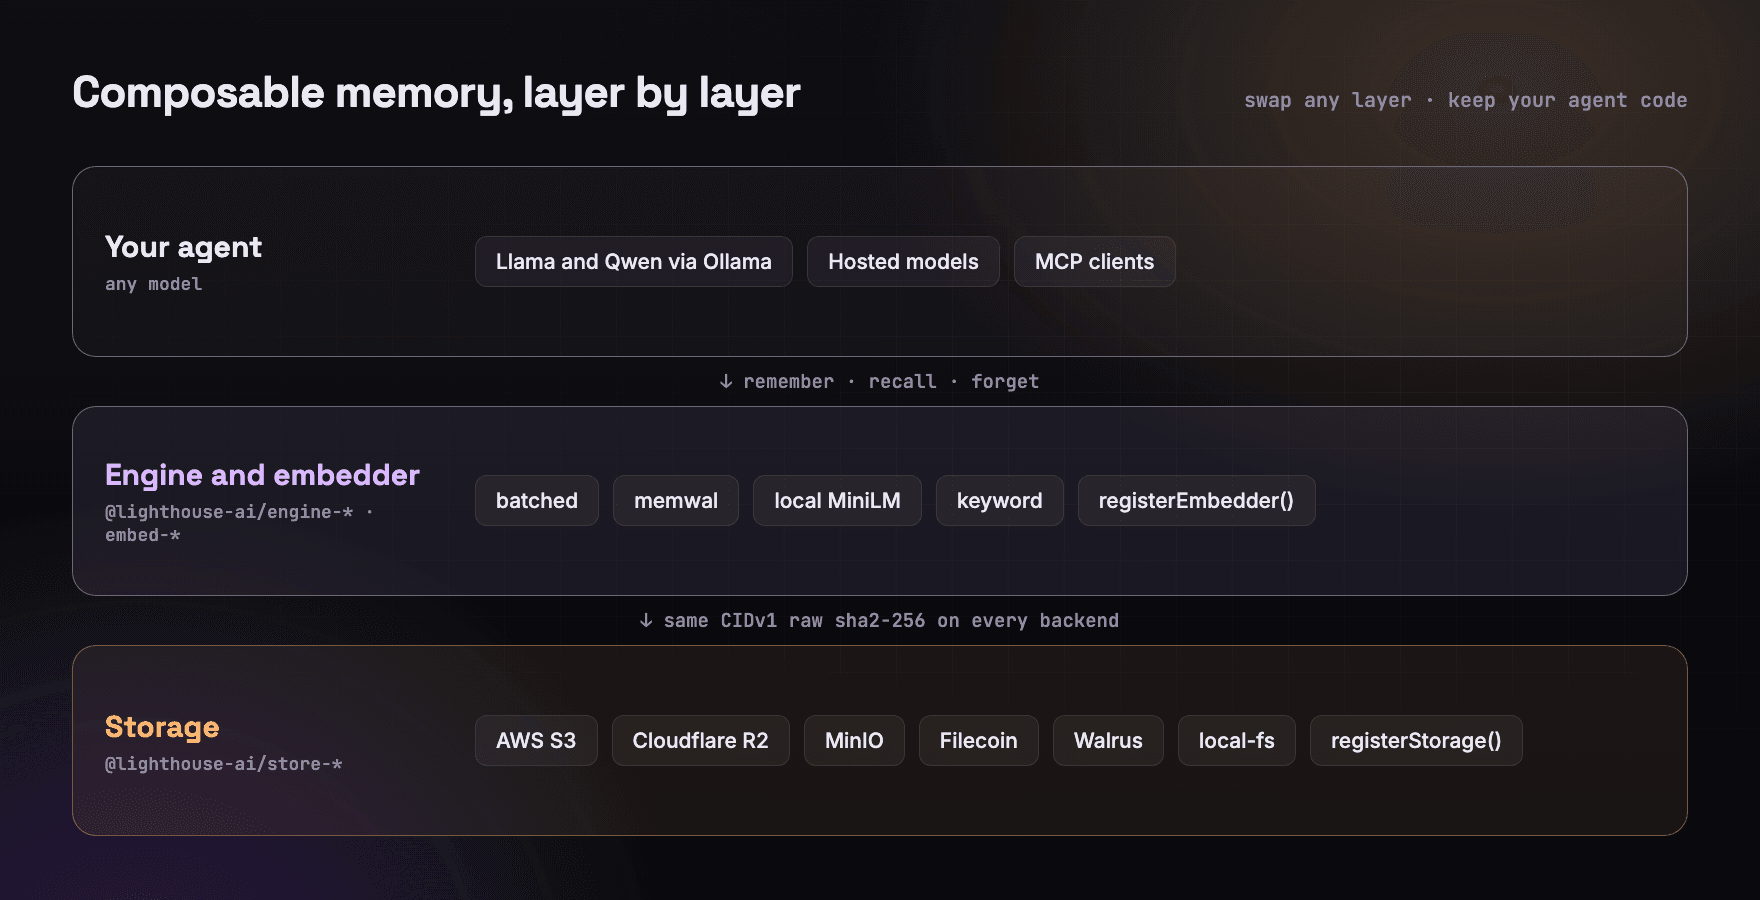
Lighthouse Memory is built as one API over swappable layers. This post shows what can be swapped, how to run memory on AWS S3, Cloudflare R2 or MinIO, how recall stays on open source models, and how to write your own adapter.
What Composable Means Here
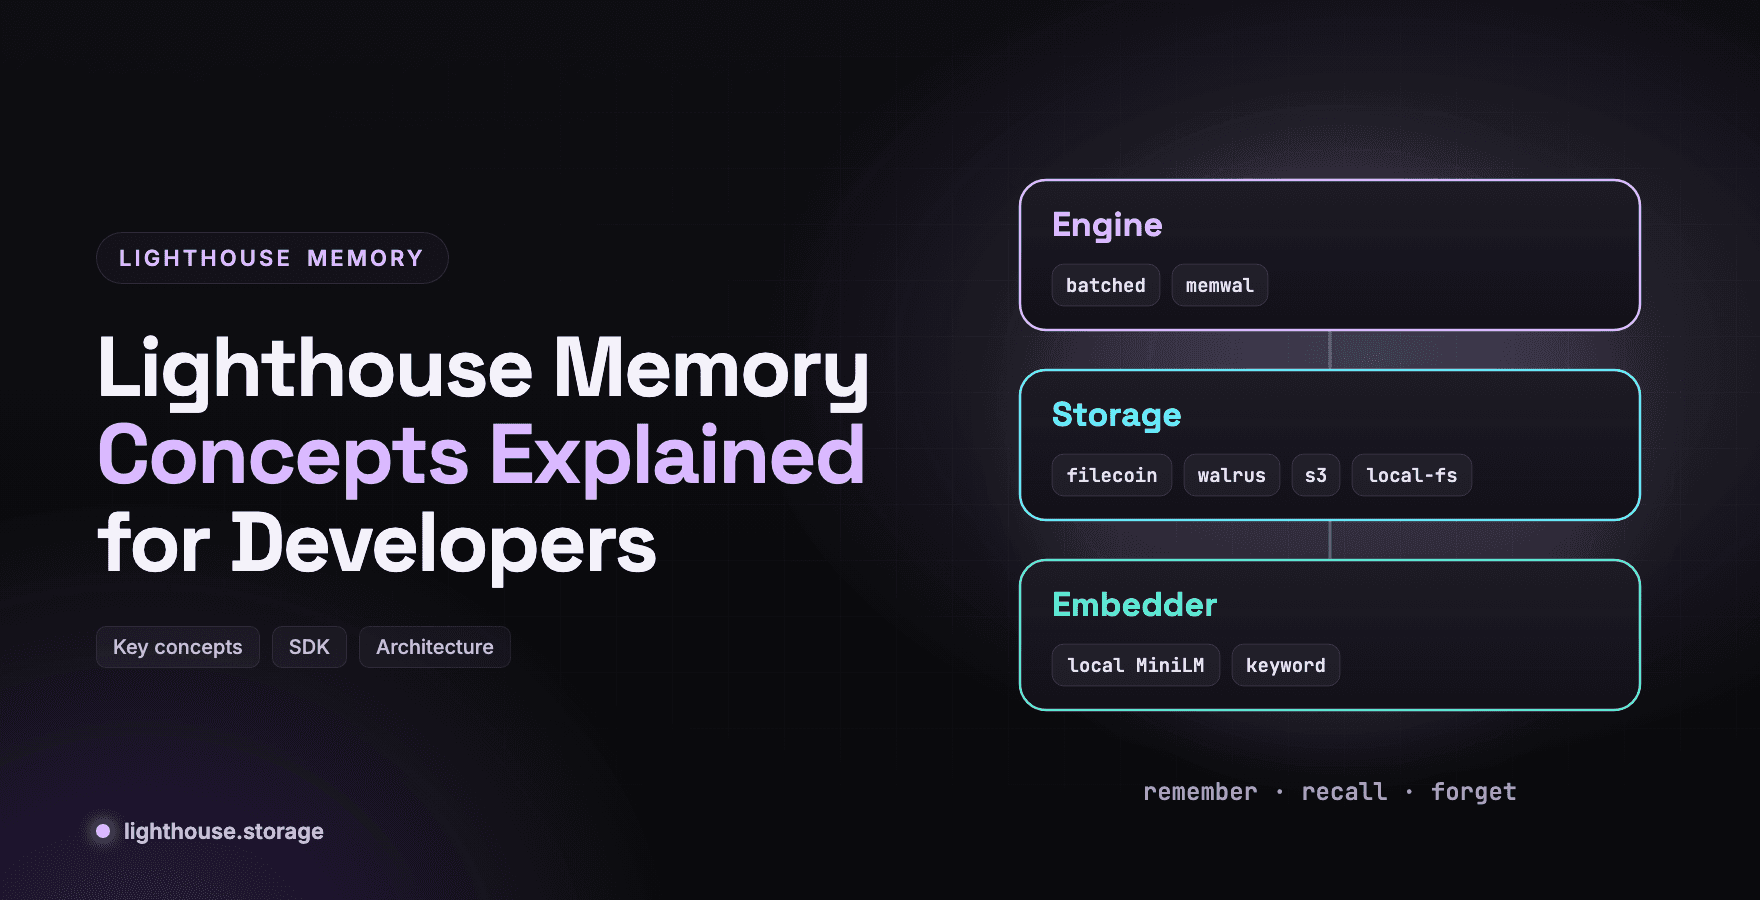
| Layer | Built in options | Swap with |
|---|---|---|
| Engine | batched (local, any storage), memwal (encrypted relayer on Walrus) | MEMORY_ENGINE |
| Storage | lh-ipfs-filecoin, lh-ipfs-walrus, s3 (AWS, R2, MinIO), local-fs | MEMORY_STORAGE |
| Embedder | local (open source MiniLM, in process), keyword (zero dependencies) | MEMORY_EMBEDDER |
| Index store | Local JSON file | indexStore option (for example, DynamoDB) |
| Your own | Any storage or embedder | registerStorage(), registerEmbedder() |
The packages are MIT licensed and published separately on npm, so you install only what you use. @lighthouse-ai/core never imports the others.
Memory on AWS S3, Cloudflare R2 or MinIO
The s3 storage adapter speaks the S3 API, so the same code runs against AWS S3, Cloudflare R2 and self hosted MinIO. It reads everything from the environment.
npm install @lighthouse-ai/core @lighthouse-ai/engine-batched @lighthouse-ai/store-s3 @lighthouse-ai/embed-local dotenv
# AWS S3
S3_BUCKET=acme-agent-memory
S3_REGION=us-east-1

# Cloudflare R2
# S3_ENDPOINT=https://<account>.r2.cloudflarestorage.com
# S3_FORCE_PATH_STYLE=1

# MinIO (local, zero cloud cost)
# S3_ENDPOINT=http://localhost:9000
# S3_FORCE_PATH_STYLE=1

# Optional
# S3_PREFIX=memory-sdk
# S3_PUBLIC_BASE_URL=https://cdn.example.com/memory
import 'dotenv/config'
import '@lighthouse-ai/store-s3'
import '@lighthouse-ai/embed-local'
import { createStorage, createEmbedder } from '@lighthouse-ai/core'
import { BatchedEngine } from '@lighthouse-ai/engine-batched'

const storage = await createStorage('s3', {}) // reads S3_* from env
const memory = new BatchedEngine(storage, { namespace: 'support', embedder: await createEmbedder('local') })

await memory.remember('Enterprise customers get a named CSM and 4 hour response SLA.', { tags: ['policy'] })
await memory.flush()
await memory.rebuild() // proves the bucket alone is enough to restore memory
How memory is laid out in your bucket
Objects are content addressed, not sequential:
<prefix>/blobs/<cid>.jsonholds each batch blob. Same content, same CID, deduplicated naturally.<prefix>/names/mem-batch.<namespace>.<batchId>.jsonis an alias used for listing and rebuild.
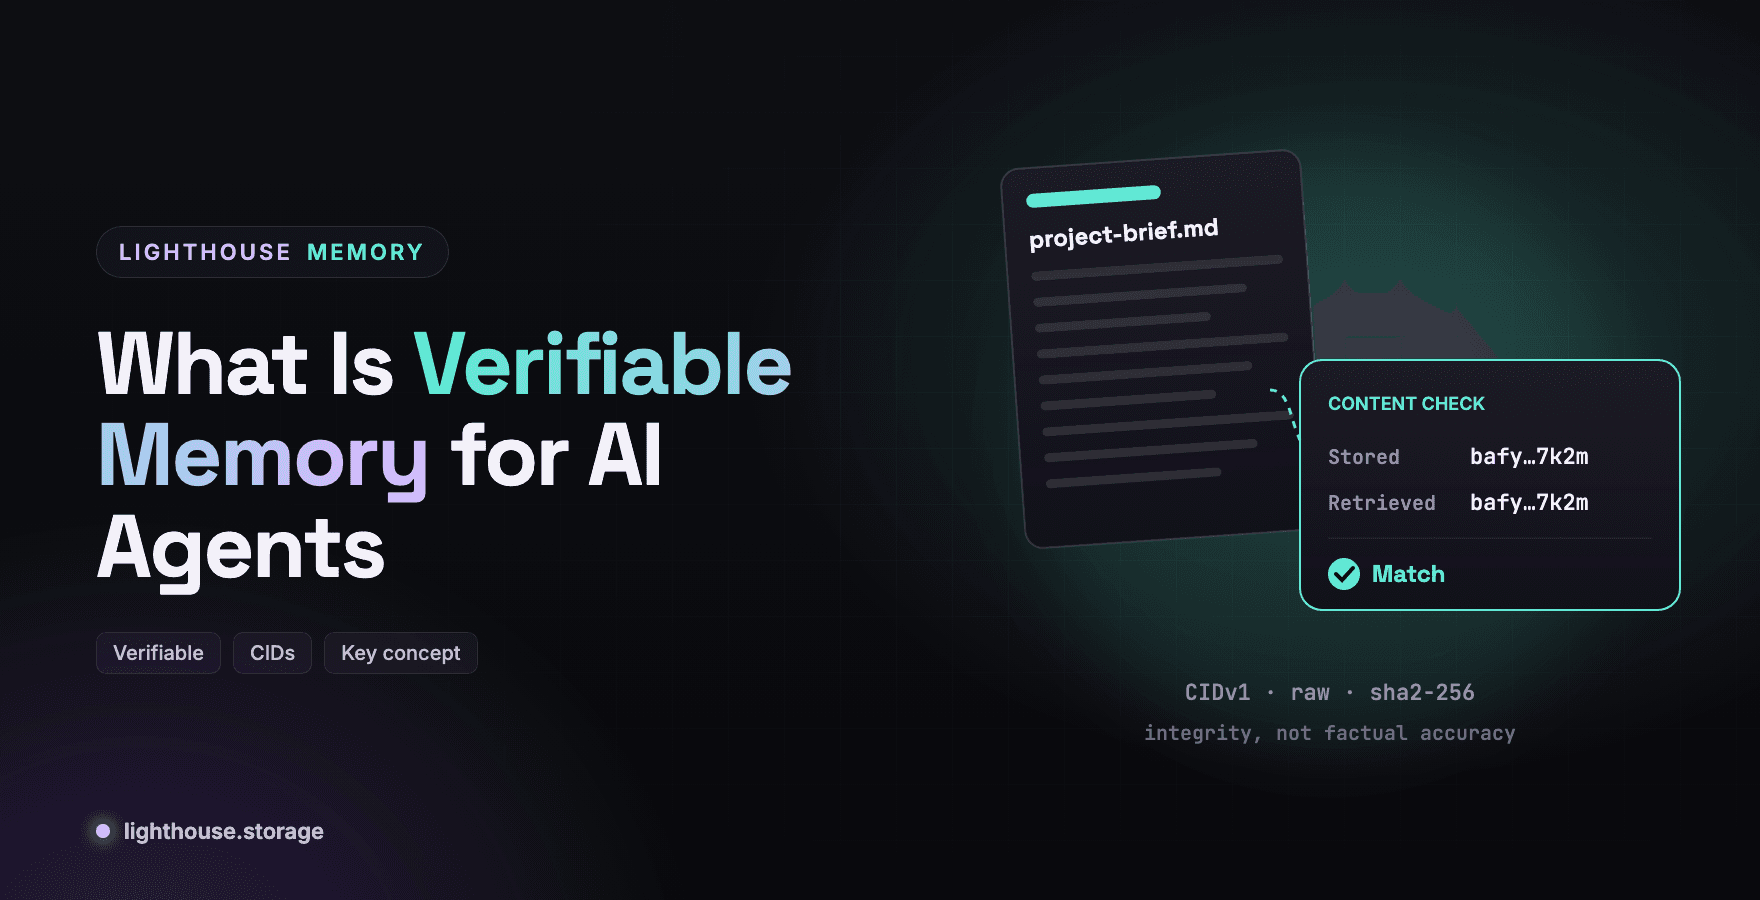
The adapter computes the same CIDv1 raw sha2-256 CIDs as every other storage. A memory stored in S3 has the same CID it would have on Filecoin. Verification works identically, and moving between backends does not change identifiers.
What changes on S3
| Lighthouse storage | S3, R2, MinIO | |
|---|---|---|
forget() | Stops renewal; readable until the period expires | Hard delete once no memory references the blob |
| Public gateway | Built in | Set S3PUBLICBASE_URL for HTTPS links |
| Walrus blob IDs | On lh-ipfs-walrus | Not applicable |
| Quota | Real bytes on Filecoin; about 63 MB per blob on Walrus | Your bucket |
| Rebuild speed | Lists and fetches every blob | Usually faster; S3 listing is cheap |
Hard deletes are why regulated teams often choose S3 or R2. When a user asks to be forgotten, forget() really removes the bytes.
Recall on Open Source Models, Fully Local
The default local embedder runs all-MiniLM-L6-v2, an open source sentence embedding model, in process via Transformers.js. The roughly 25 MB weights download once, then recall runs offline. No content leaves the machine, and there is no embedding API key.
Ranking is hybrid, so it stays robust even for short or unusual queries:
score = 0.7 × cosine(query, memory) + 0.3 × min(1, keywordScore)
If you need zero dependencies, for CI, edge functions or air gapped machines, pass embedder: null for keyword and tag matching only.
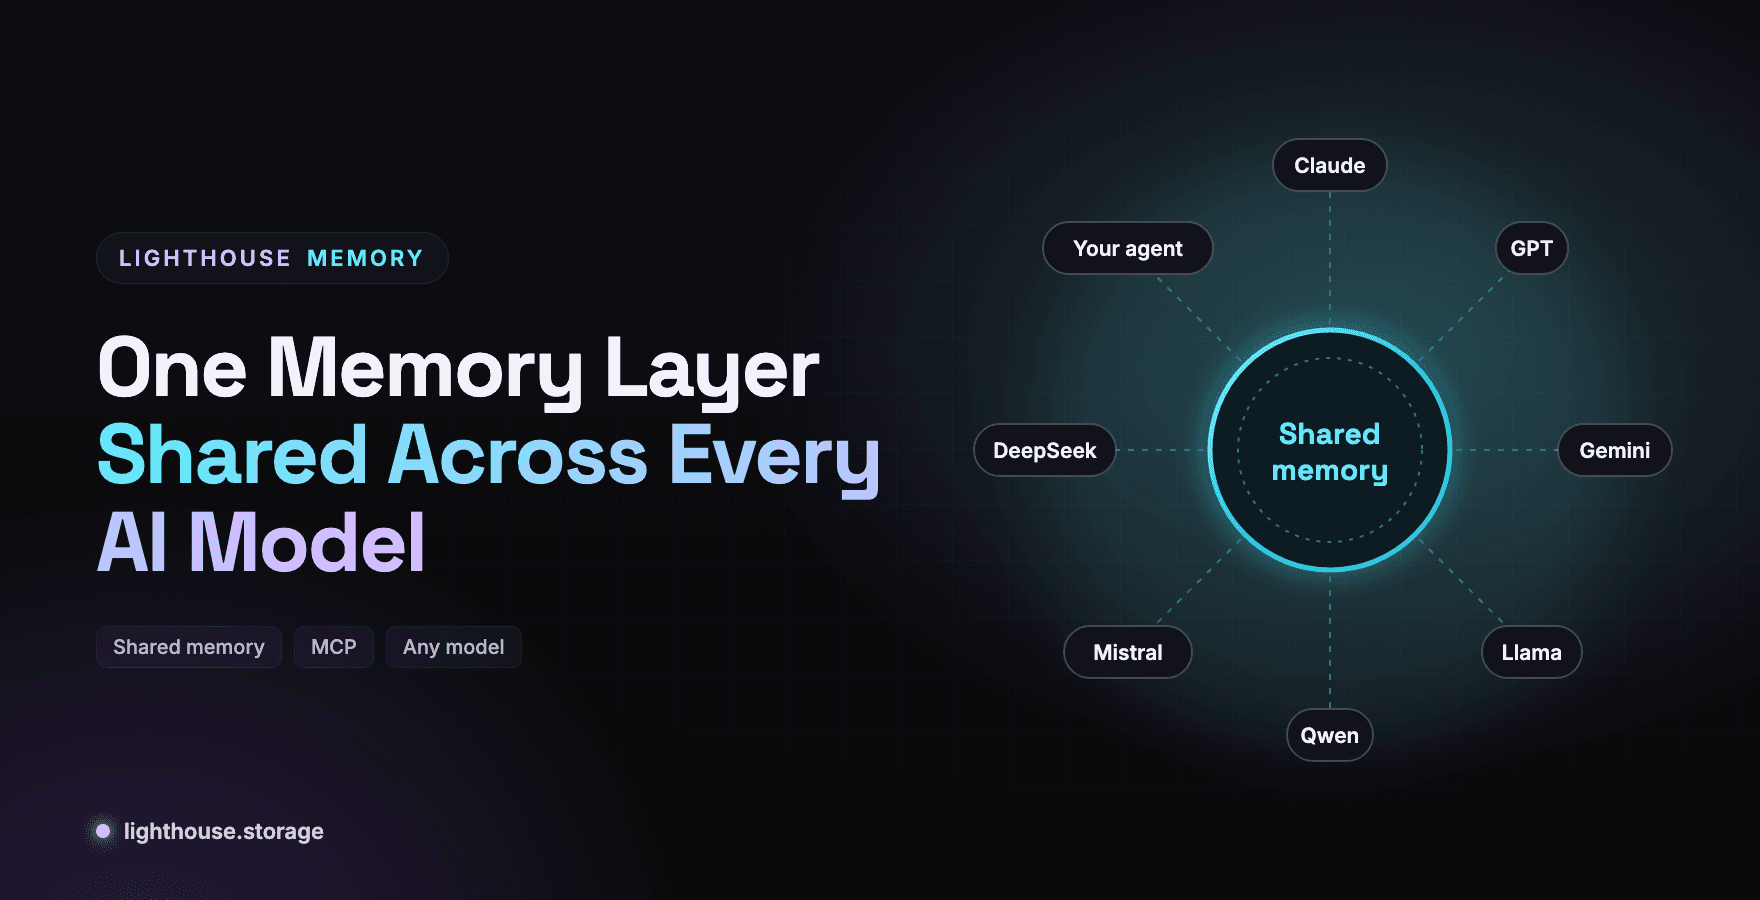
The generation side is equally open. Lighthouse Memory does not call a language model. Your agent can run on Llama, Qwen, Mistral or DeepSeek through Ollama or vLLM, recall context from memory, and put it in the prompt. Memory and model are independent choices. See One Memory Layer Shared Across Every AI Model.
Bring Your Own Adapter
When the built in options are not enough, the registry lets you add a layer with one call. The docs describe it this way: adding a layer is one registerStorage or registerEmbedder call.
import { registerStorage, registerEmbedder } from '@lighthouse-ai/core'

// GcsStorage and OllamaEmbedder are your own classes
registerStorage('gcs', (opts) => new GcsStorage(opts))
registerEmbedder('ollama-nomic', (opts) => new OllamaEmbedder({ model: 'nomic-embed-text', ...opts }))
A storage adapter implements the same surface every built in adapter exposes: name, capabilities, gatewayUrl(cid), uploadJson(value, fileName), fetchJson(cid), listAllFiles(), deleteFile(fileId) and getBlobIds(cid). Keep one rule from the docs: CIDs are CIDv1 raw sha2-256 and must stay stable, so compute them the same way the other adapters do.
Two cautions for custom embedders. Vectors carry their model ID and recall only compares same model vectors, so switching embedders falls back to keyword scoring until memories are re-embedded. And a remote embedding API means memory content leaves your machine, which removes one of the local embedder's guarantees.
Swap Backends Without Touching Agent Code
Because every layer is chosen by configuration, the same agent can move through environments:
# Development: offline, no keys
MEMORY_STORAGE=local-fs MEMORY_EMBEDDER=keyword

# Staging: your MinIO
MEMORY_STORAGE=s3 S3_ENDPOINT=http://minio:9000 S3_FORCE_PATH_STYLE=1 S3_BUCKET=staging-memory

# Production option A: your R2 bucket
MEMORY_STORAGE=s3 S3_ENDPOINT=https://<account>.r2.cloudflarestorage.com S3_FORCE_PATH_STYLE=1 S3_BUCKET=prod-memory

# Production option B: decentralized and verifiable by anyone
MEMORY_STORAGE=lh-ipfs-filecoin LIGHTHOUSE_API_KEY=lh_...
Namespaces stay isolated per storage: memories written to one backend are recalled and rebuilt from that backend only.
Frequently Asked Questions
Can I store AI agent memory in my own S3 bucket?
Yes. The s3 adapter works with AWS S3, Cloudflare R2 and MinIO, configured with S3_* environment variables.
Does Lighthouse Memory need an embedding API? No. The default embedder runs the open source all-MiniLM-L6-v2 model locally, and keyword mode needs no model at all.
Which language models does it work with? Any. Memory stores and recalls context; your agent can use any open source or hosted model to generate.
Do memory CIDs change if I switch from S3 to Filecoin? No. Every adapter computes the same CIDv1 raw sha2-256 CIDs, so the same content has the same identifier everywhere.
Can I write my own storage adapter?
Yes. Implement the storage interface and register it with registerStorage() from @lighthouse-ai/core.
Get Started
Concepts behind every layer: Lighthouse Memory Concepts Explained for Developers.
Stay in Touch
Learn more at the website, docs, or GitHub. Join the community on Discord, X, Telegram, and LinkedIn.